There are two of browsers, and they share a codebase.
The first runs on an ESP32-S3: a microcontroller, about £25, 8MB of PSRAM, driving an 800x480 panel. It renders real websites.
At the point where I was beginning to feel the constraints of the ESP32 platform, I switched horses to MacOS and forked the same engine. That version passes 84.5% of the Web Platform Tests - 8,591 of 10,162, measured over seven WPT directories (css/CSS2, css-backgrounds, css-color, css-flexbox, css-text, css-values and html/rendering) rather than the whole of WPT. Neither has a line of WebKit, Blink or Gecko in it. The ESP32 version is 100% homespun code, the MacOS version does leans on one third party library, Brotli. Obviously there are dependencies on MacOS OS services (nerworking, core graphics, cocoa etc.) to render images, but there's no webkit or similar in the MacOS version of my browser.
That is the context. I think the more interesting part is how the work got done, from a software development approach - the overall approach proved sound and got me further than I expected in terms of the end-game of a usable web browser from scratch.
Start at 80:20 and mean it
The first goal was not a browser. It was legible text on a screen from a real URL: HTTP, a tokeniser, a tree builder, a box model with block and inline layout, and a font. No floats, no tables, no positioning, no scripting.
That put real pages on the panel far sooner than felt reasonable, and it set the pattern for everything after - build the thing that renders something, find out what it gets wrong, fix that. The alternative is to implement CSS 2.1 properly and then start rendering, which never finishes, because there is no feedback until the end.
The price is being willing to bin the scaffolding. The first line-breaker knew about spaces and nothing else. It was replaced twice, and both replacements happened because a test suite told me exactly which 1,700 of 19,332 Unicode cases it was failing.
Except for JavaScript, where 80% is useless
Everywhere else a partial implementation degrades gracefully. A missing CSS property means the page looks wrong. A missing bit of JavaScript means the page does not work at all, and it usually fails in a way that gives you no clue which bit was missing - a script throws on line 1 of a minified bundle and 200KB of behaviour silently never happens.
The JS engine therefore got a different standard: correctness first, breadth second, and never ship a half-implemented builtin. It sits at 907 of 952 on the compatibility table, with regular expressions complete, and the remaining 45 are three structural items rather than a long tail, which is the position you want, because you can point at them.
A language engine is the one component where "mostly works" is worse than "not implemented". A missing function throws a clean ReferenceError you can find in a minute. A subtly wrong one corrupts a result three call frames later.
Wire up the official test suites the day a component can run one
Not when it is finished. The day it can run one at all.
The engine is checked against Web Platform Tests, test262, the Unicode line-breaking and grapheme-breaking suites (UAX 14 and 29), html5lib's tokeniser and tree-construction tests, the CSS parsing tests and the public suffix list. Every one of them found things I would never have thought to look for, and each gives a number that moves.
One warning. A suite that cannot fail is worse than no suite. Two of the Unicode suites here were reported green by four separate work sessions without executing a single case: the data files had been fetched by hand into one working tree, years of habit assumed they were there, and the test printed "SKIP" and returned success. Nineteen thousand cases, all passing, none of them run. Break a test on purpose occasionally and check that it goes red.
Put it side by side with a real browser
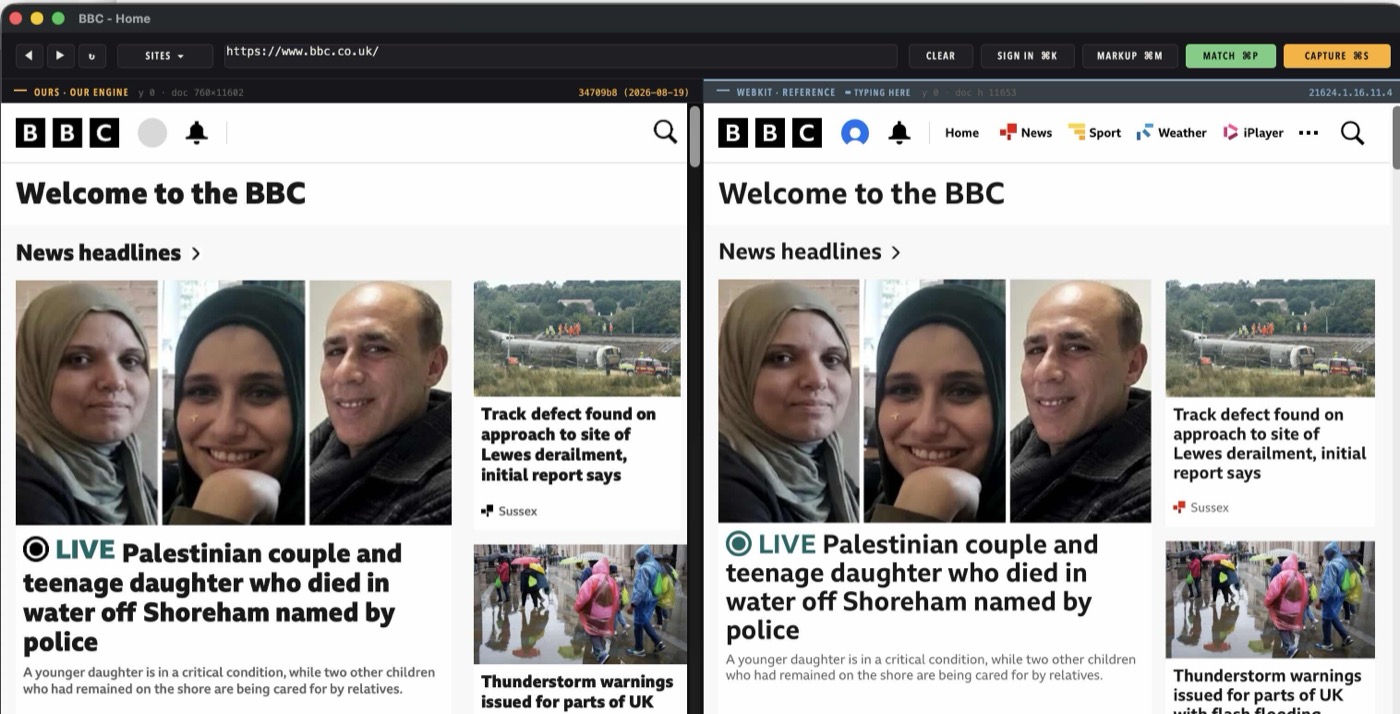
webcompare: the same page, our engine on the left, WebKit on the right.
The tool I would build first next time is webcompare. It loads the same URL twice on the same machine at the same viewport, our engine in one pane and WebKit in the other.
A pixel diff against a reference tells you that a page is wrong. Two renderings next to each other tell you what is wrong, immediately and without instrumentation. Nearly every layout bug of any subtlety in this project was found by looking at that split screen rather than by reading a failure count: text sitting a few pixels low, a float on the wrong side, a table border straddling the wrong edge, a sticky header trailing down the page.
A 50% compliant browser renders the web perfectly legibly
At around 50% on the Web Platform Tests the browser rendered real sites - news, blogs, documentation - in a way you could read without complaint. Headings were headings, paragraphs flowed, links were blue, images were where they should be. Shown it cold, most people would have said the fonts looked a bit off.
The web's bulk is a small number of features. Block and inline layout, the box model, floats, basic typography and a handful of colour and background properties will render most of most pages. The long tail of the specification is the long tail for a reason.
Which makes the pass rate a proxy rather than the goal, and that is uncomfortable if you like round numbers. Going from 50% to 84.5% did not make pages 70% more readable. It fixed a very large number of individually small things - a collapsed table border drawn on the wrong side, line-height: 1.5 inherited as pixels instead of as a ratio, an <ol type=A> numbering itself a, b, c. All real bugs, all worth fixing, none of them what makes a browser usable.
The test harness is a component with its own bugs
Don't treat it as infallible - I did at the start, and learned two things along the way.
The first is watching for false passes. A reference test renders the test page and a reference page with the same engine and compares the two, so if the engine gets both wrong in the same way, the test passes. Nine confirmed instances here. The nasty consequence is that fixing a real bug can lose you tests - the test half becomes correct while the reference half stays wrong, so the score goes down because the engine got better. Any suite built this way needs that stated loudly, or people optimise for the number.
The second is suspecting the instrument first. Twenty-three times now, a number that would not move has turned out to be the harness rather than the engine. A sweep once reported 250 crashes; every one was signal 9, the OOM killer, because I had run it on a loaded machine. A "4x performance regression" I chased for an hour was my own debug build compared against an optimised one. A bug I confidently wrote up as memory corruption in a core class was a one-definition-rule violation I had introduced myself twenty minutes earlier, by defining a constant for some translation units and not others when that constant sized a member array. An audit of the runner itself found six faults nobody was looking for, including three tests that passed by rendering nothing at all against a reference that was a zero-byte file.
The tell, every time, was an impossibility rather than an implausibility - a crash column that should have been zero, a negative duration, a bisect naming a commit that only adds a shell script. Implausible numbers get rationalised. Impossible ones cannot be.
Measure what you are actually waiting for
At 84.5% the engine was correct enough to be useful and slow enough to be annoying, so I went looking for performance. Leaving instrumentation and fine tuning to this point was a conscious decision, layout optimisations can obfuscate the code base and add further complexity that makes getting the basics right harder. My gut told me layout was the issue. It was not. Layout is linear at about 41 microseconds per element; a 4,000-cell table costs 0.11 seconds. In order of size, the actual causes were:
a hardcoded 900ms sleep after page load, waiting for late scripts. Sound reasoning for real websites, pure waste for a test corpus, and worth about five CPU-hours per full run.
registering 78 web fonts at every process start, about 4.6ms each.
a serial fetch queue. BBC News needs 55 ES modules and they were fetched one at a time. The page never finished loading at all, so every measurement I had of it was the 60-second timeout rather than the page.
no connection reuse: a fresh TCP connection and TLS handshake per subresource.
an HTTP cache that already existed, passed 45 of its own tests, and had never once been called by the macOS port. It was written for the microcontroller, where a fetch costs seconds, and the desktop port simply never wired it up.
Together, a full test sweep went from 41 minutes to 2.5. BBC News went from never completing to 11.5 seconds warm. lobste.rs went from 5.65 seconds to under half a second.
The lesson is not "profile before optimising", which everybody says already. 93% of that page load was the process sitting idle, and no amount of profiling the layout engine would have found it, because the layout engine was not running.
Ask what shape of bug the suite cannot see
The worst user-visible bug of the whole exercise was a site's sticky masthead repeating down the page as you scrolled - dozens of copies, completely unusable.
Every reference test renders the whole document in a single pass. An interactive window does not; it repaints the rectangle that got damaged. Those are different code paths, and position: fixed and position: sticky only go down the second one. 8,591 passing tests had nothing to say about it and structurally never could.
More conformance tests would not have helped. What helped was a different kind of check: render the same page twice, once whole and once in eight strips, and require the pixels to be identical. That needs no reference page at all, so unlike a reftest there is nothing that can be wrong in agreement with you.
Once a suite gets large, the question is what shape of bug it cannot see. The answer is rarely "none", and it is usually where the users are.
Code size
Excluding tests, tooling and vendored libraries, the whole thing is 140,235 lines: 84,894 of code and 46,665 of comment. A third of it is comment.
Rough published figures for comparison, counted inconsistently - some are the whole repository, some the engine only, some include dependencies and tests and some do not:
Chromium, whole repo: ~32 million
Blink, the rendering engine on its own: ~5 million
Gecko: ~20-30 million
WebKit: ~10-15 million
Servo: ~500,000
NetSurf: ~200,000
That puts this at roughly a sixtieth of Blink and about 0.3% of a full Chromium checkout. Not like for like, in fairness: those engines carry WebRTC, WebGL, video codecs, sandboxing, multi-process architecture, accessibility and decades of compatibility workarounds for real sites, and they are production software with real security models. The narrower claim is the one worth making - the part that renders a legible web page is much smaller than the size of a modern browser suggests.
The 33% comment figure is deliberate. The comments record why, and particularly why the things that look wrong are right - why this loop runs backwards, why that value is clamped before the transform rather than after, why the obvious simplification breaks tables. I have come back to this code after long gaps and been able to pick it straight up again, and I put that almost entirely down to the comments.
Would I do it again?
I started this project as a 'because I can' type exercise. I didn't think a working, usable browser was a given, but thought it would be instructive to have a go. I learned a lot along the way, and did actually end up with a usable browser, which is a bonus. Would I do it again? Yes, and largely the same way. Ship something that renders, put it next to a real browser, wire the official suites in early, hold the language engine to a higher standard than everything else, and keep a written record of every occasion the measurement turned out to be wrong, because it will be wrong far more often than feels reasonable. Roughly a quarter of the total effort here went into fixing things that were never broken, and almost all of that was avoidable.